A single-node database becomes a single point of failure the moment your data outgrows one machine, and rewriting an application around a new query language to fix that is rarely an option. TiDB was built to solve that specific problem: a distributed SQL database that scales horizontally while staying compatible with the MySQL protocol you already use. This piece walks through the three components that make that possible and how they hold together under node failure.
What Is TiDB’s Distributed SQL Architecture?
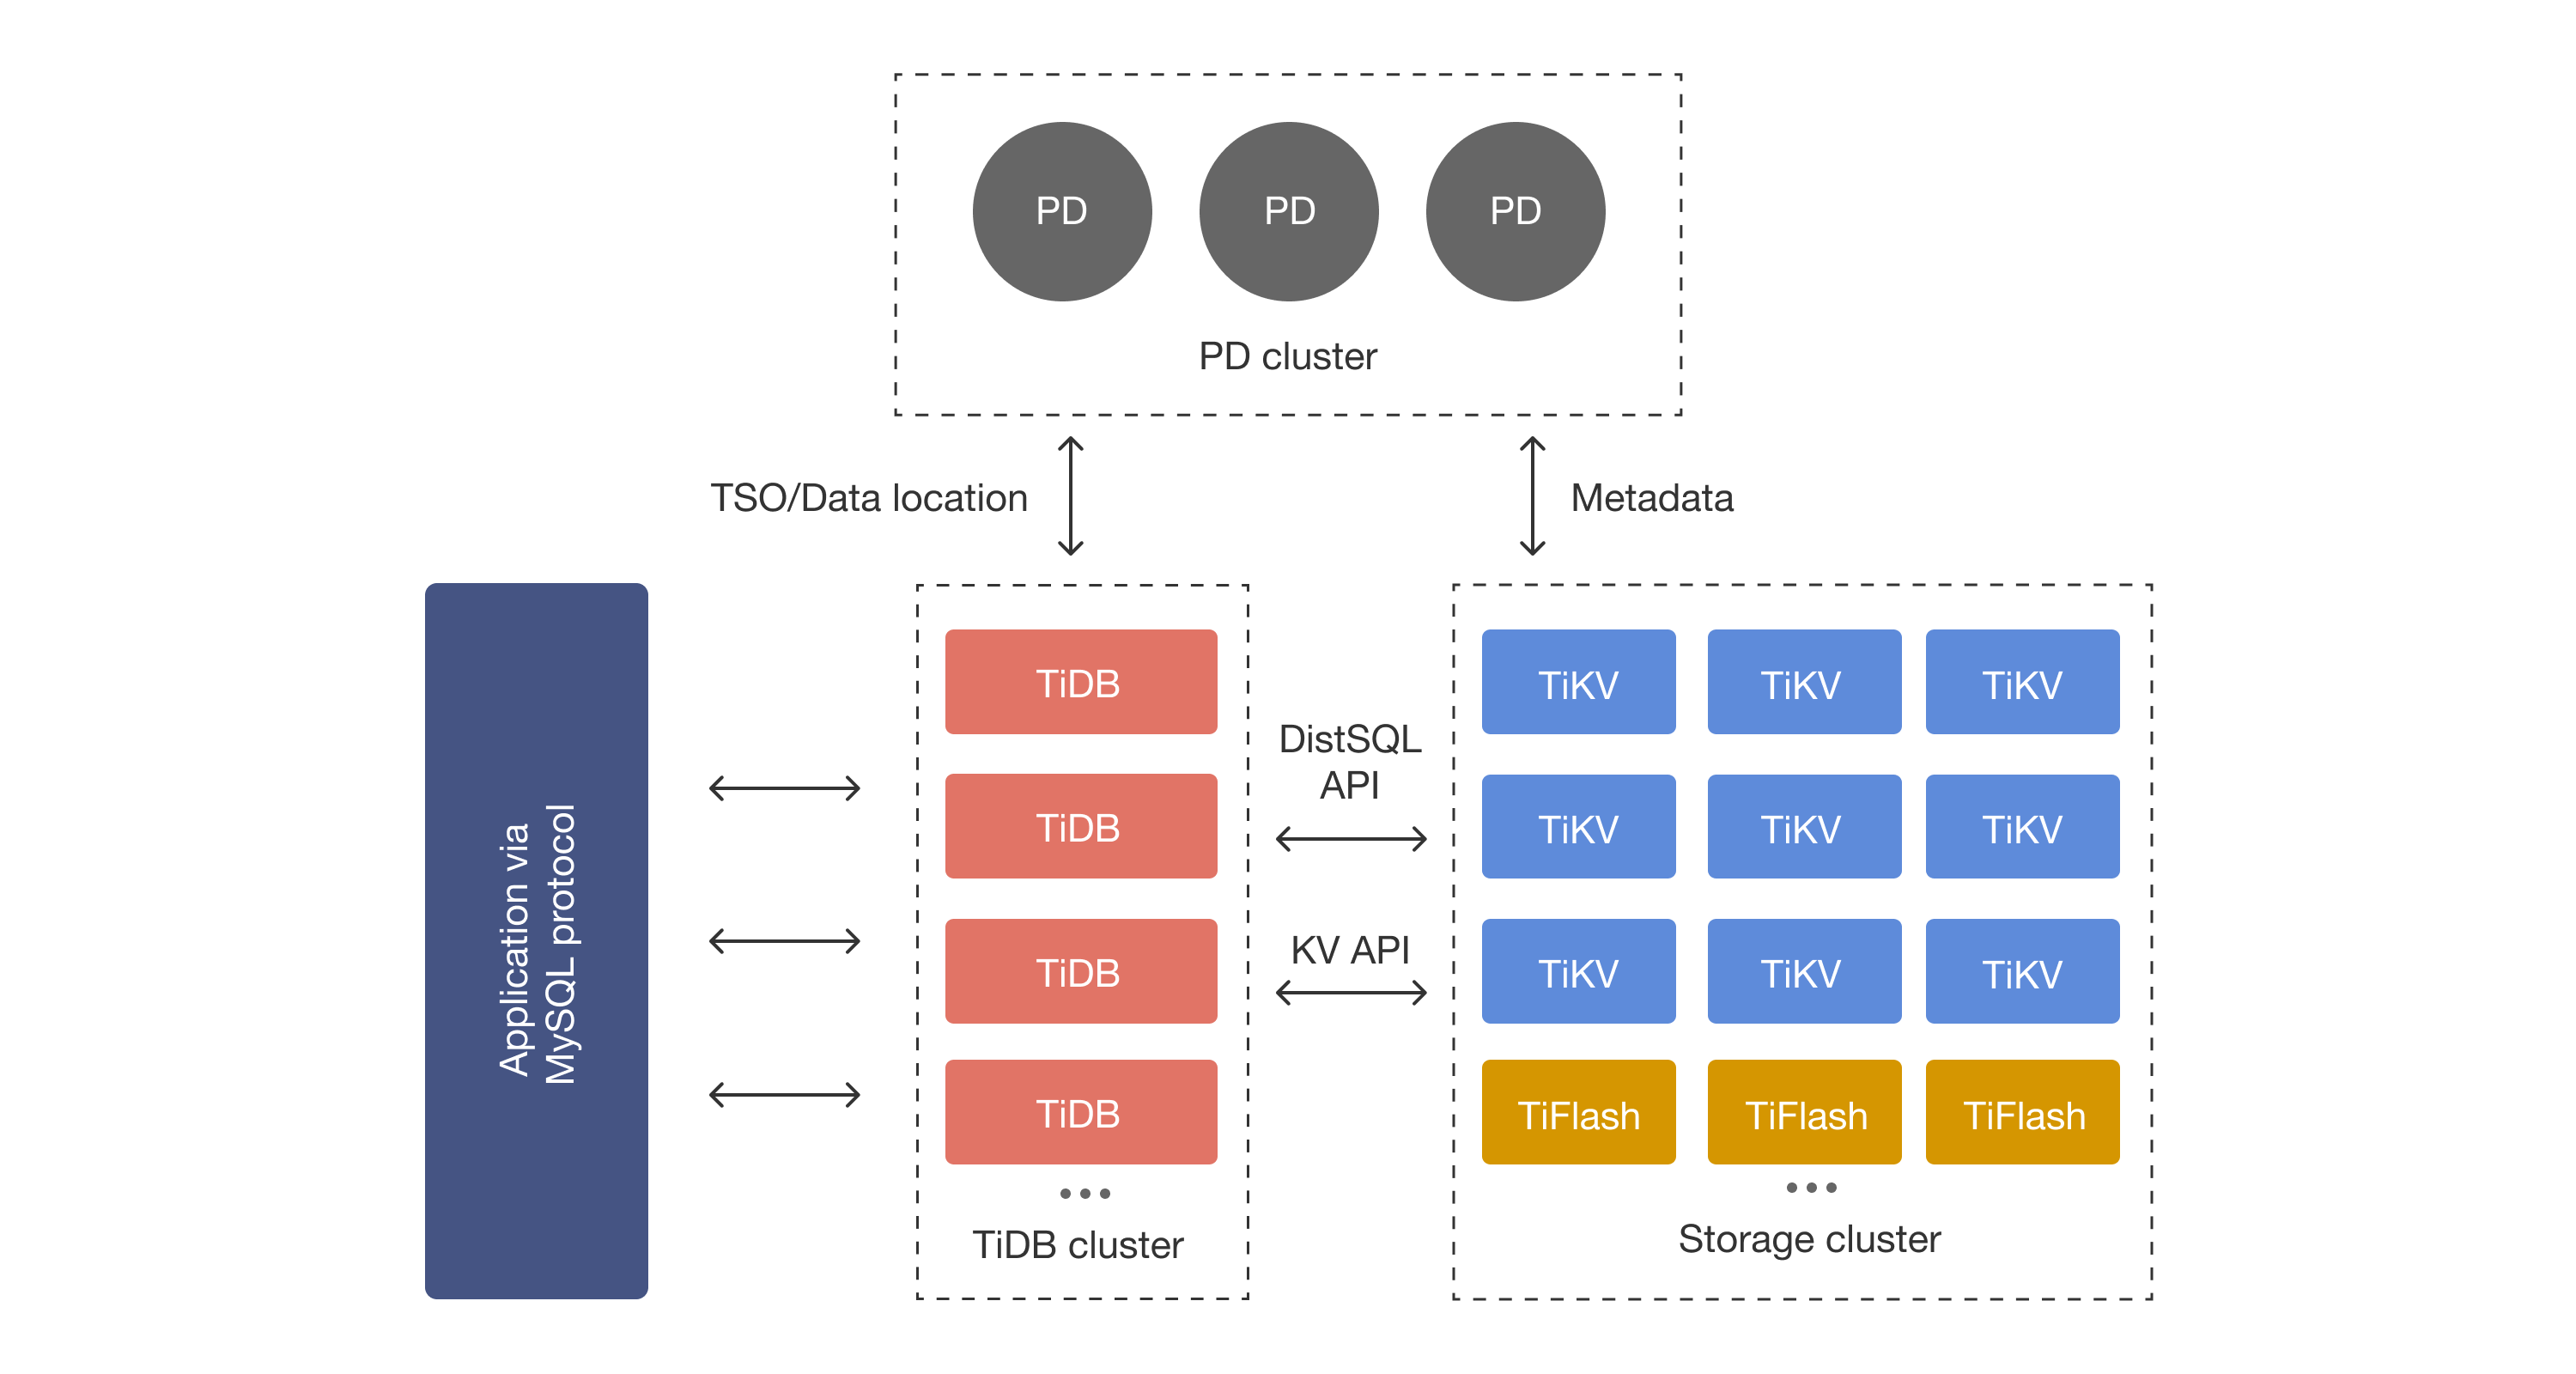
TiDB’s architecture separates three concerns into three component types: the TiDB Server handles SQL parsing and query planning, TiKV stores the actual data as a distributed key-value store, and the Placement Driver (PD) manages cluster metadata and data placement. Each component type scales independently, so adding compute or storage capacity never requires resharding data by hand.
TiDB’s Key Components
The architecture of TiDB consists of several key components that work in cohesion to deliver a reliable database solution: the TiDB Server, TiKV, and the Placement Driver (PD).
TiDB Server: SQL Processing Layer
The TiDB server acts as the SQL layer, managing client requests and generating execution plans for SQL queries. It is stateless, meaning it does not store data but handles SQL parsing, optimization, and execution plans. By separating compute from storage, the TiDB server is intrinsically scalable, and it provides a unified interface to applications through load balancing components such as Linux Virtual Server (LVS) and HAProxy.
TiKV: Distributed Storage Engine
TiKV serves as the distributed storage engine for TiDB, responsible for storing data persistently. It is a key-value store built on the Raft consensus algorithm, ensuring data consistency and high availability. Each piece of data is stored in a region, and each region is replicated across three nodes by default. TiKV supports ACID transactions with snapshot isolation, enabling distributed transactions at the SQL level.
Placement Driver (PD): Cluster Management
The Placement Driver (PD) manages cluster metadata, coordinates distributed transactions, and dynamically allocates transaction IDs. PD servers store metadata on data distribution and topology, and they monitor and balance the cluster by scheduling data across TiKV nodes based on real-time metrics.
Data Distribution and Replication in TiDB
Sharding and Automatic Data Distribution
TiDB automatically shards tables into smaller chunks known as regions. Each region is a contiguous range of rows, managed independently. This approach distributes data across many nodes, providing balanced workload distribution and preventing bottlenecks. As data grows, regions split and redistribute dynamically, keeping data access and storage efficient.
Consistent Hashing and Region Split
Consistent hashing manages the dynamic partitioning of key spaces across distributed nodes. When a region exceeds a certain size (96 MB by default), it automatically splits into two smaller regions, which are then distributed across different nodes for load balancing and scalability.
Raft Protocol for Data Replication
The Raft protocol is central to TiDB’s reliability and data consistency. Raft achieves consensus among distributed nodes, ensuring that all replicas of a region hold the same data. In a Raft group, a leader elected through consensus handles client requests and log replication, and a majority of replicas must agree before a transaction commits.
# Example: Checking Raft Leader in TiKV
tikv-ctl --host <TiKV-node-ip> raft --region <region-id> --show-region-id
How TiDB’s Raft Architecture Solves Distributed Consistency
Replicating data across many nodes creates a specific risk: replicas can drift out of sync, or a network partition can leave two nodes both believing they’re the leader. TiDB avoids this with a multi-Raft group architecture, where each region runs its own independent Raft group, so a delay or failure in one group never blocks the others. If a region’s leader becomes unavailable, Raft elects a new one from the surviving replicas automatically, and a transaction only commits once a majority of replicas confirm it, which is what keeps reads consistent even mid-failover.
-- Example: Starting a Transaction in TiDB
START TRANSACTION;

-- Example: Performing a Write Operation
UPDATE users SET balance = balance + 100 WHERE user_id = 1;

-- Example: Committing the Transaction
COMMIT;
Rakuten relies on this multi-Raft design to keep its loyalty program’s transactional data consistent while scaling out, without the manual failover runbooks a single-leader architecture would require.
Key Query Performance
Load balancing components like LVS and HAProxy distribute incoming requests across TiDB servers so no single instance becomes a bottleneck as traffic grows. TiDB also applies cost-based query optimization and secondary indexes to generate efficient execution plans, and the TiFlash columnar engine accelerates analytical queries without touching the transactional path.
-- Example: Creating an Index in TiDB
CREATE INDEX idx_user_balance ON users(balance);

-- Example: Optimized Query Using Indexes
SELECT * FROM users WHERE balance > 1000;
FAQ
What are the three main components of TiDB’s architecture?
- TiDB Server, a stateless SQL processing layer
- TiKV, a distributed key-value store for transactional data
- Placement Driver (PD), which manages metadata and data placement
- Each component type scales independently of the others
How does TiDB achieve strong consistency across nodes?
- Every data region replicates via the Raft consensus protocol
- A transaction commits only after a majority of replicas confirm it
- Each region runs its own independent Raft group (multi-Raft)
- A failed leader triggers automatic election of a new one from surviving replicas
Can TiDB scale without downtime?
- Yes, nodes can be added or removed while the cluster stays online
- PD rebalances data across nodes automatically as capacity changes
- Regions split automatically once they exceed 96 MB by default
- Compute and storage scale independently of each other
Is TiDB compatible with existing MySQL applications?
- Yes, TiDB supports the MySQL wire protocol
- Most existing MySQL client libraries and tools work without modification
- Migration typically requires minimal application code changes
- Full compatibility details are in the TiDB docs
Building on an Architecture Designed to Fail Gracefully
TiDB’s three-component split and multi-Raft replication mean node failure is something the architecture handles by design, not something your team has to script around. Start a free TiDB Cloud Starter cluster to see the Raft failover behavior firsthand against your own workload.