Trusted by Teams Building on TiDB


Serverless Auto-Scaling for HTAP Workloads
TiDB Cloud Starter is built for HTAP (Hybrid Transactional and Analytical Processing) combining OLTP and OLAP on the same distributed SQL platform so you can run real-time analytics directly on live operational data.
Built-in columnar storage supports analytical queries on transactional data, without a separate analytics database or ETL pipeline between systems.

Bigger & Better Scale
- Fully managed
- Scale from 0 to PB without changing your app
- Non-blocking schema changes
- Support high-performance analytics queries

Faster & Easier Serverless
- 25 GiB row storage, 25 GiB columnar storage, and 250M Request Units free¹
- Only pay for what you use beyond
- Scale compute to demand and down to zero when idle
- Integrate with modern stack easily like Vercel, ChatGPT, etc.
1 Monthly total per organization across up to five eligible MySQL-compatible instances. Allowances apply separately to each instance. See pricing details.

Smarter & Scalable
-
- Leverage vector search to build intelligent AI applications
- Implement Graph-based RAG for high-accuracy results
- Native integrations with leading AI vendors and frameworks
- Keep agent files across sandboxes with TiDB Cloud Filesystem
Full ACID Transactions Without Manual Sharding
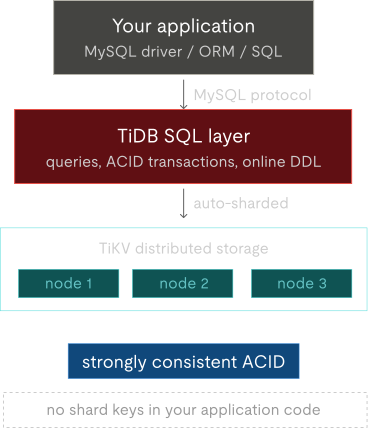
TiDB speaks MySQL and PostgreSQL, so you can build with familiar ORMs, and SQL tooling work as-is — most teams migrate without touching their application code. Data is distributed across TiKV nodes automatically. Your application never manages shard keys or routing. Transactions are strongly consistent and ACID-compliant across nodes, and schema changes run online without locking.
- Connect with any MySQL-compatible driver or ORM
- No shard keys or routing logic in your application
- Distributed ACID transactions, strongly consistent
- Online DDL: schema changes without downtime or table locks
For Teams Building Agentic Applications
We take pride in our open-source roots and developer community. TiDB Cloud Starter helps you develop queries, test database changes, connect applications to data, and understand database performance as your agentic applications evolve.

GitHub stars

Pull requests

Contributors
AI Assisted SQL Editor

Branching

Data Service

Built-in Monitoring

Vector Search for RAG & AI Apps
Most teams building AI apps end up running a separate vector store alongside their main database. TiDB removes that split. Store embeddings and relational records in the same cluster, query them together with ANN search and SQL joins, and filter by structured metadata in a single statement.
- Native vector indexing and ANN search in TiDB
- Query vectors and relational data together in standard SQL
- No separate vector store to deploy or keep in sync
- Works as the retrieval layer for RAG pipelines out of the box

Integration
Integrate with Kubernetes & Your Cloud Stack
TiDB Cloud Starter fits naturally into modern, cloud-native environments. It integrates cleanly with:
- Kubernetes-based deployment models
- CI/CD pipelines
- Observability and monitoring stacks
- Popular cloud platforms and developer tools
This makes it easy to adopt TiDB as part of an existing infrastructure without disrupting workflows.


